Memory as a Shared Space: Retrieval Interfaces and View-Filtered Indexes for Persistent Agents
October 9, 2026
An agent that serves an organisation for months is only as useful as what it can recall. Today's agent runtimes keep each agent's past conversations in its own local session store, a database file with full-text indexes, and give the agent a search tool to look things up, one call at a time. These stores grow without bound: on the runtime pool behind this study, 295 agents hold 38.5 GB of them, and the largest single store is 8.5 GB. And they are private by construction: what the user told one agent is invisible to every other agent.
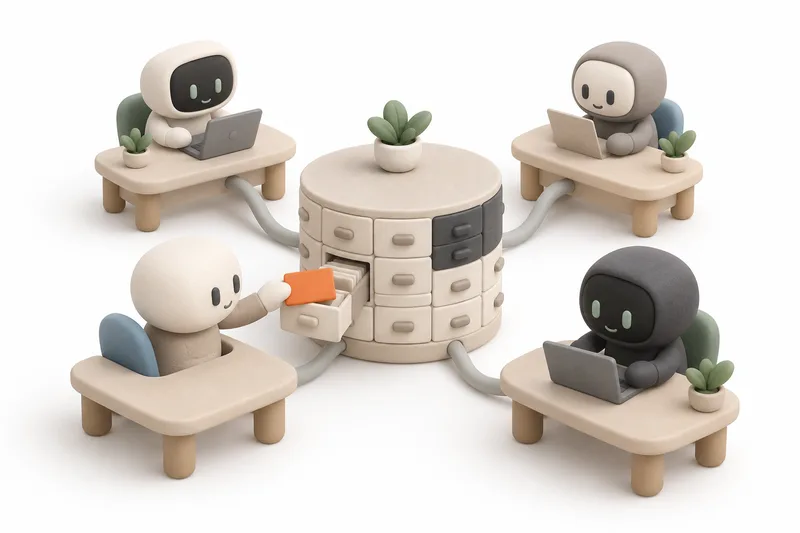
We asked what changes if memory becomes one shared space instead. Every agent's committed turns are indexed once, with lexical and dense (vector) scoring, and each agent searches through a view: its own records plus the records other agents made public. The view is checked inside the index, so private records never leave it, whatever the model asks for.
How we tested it
We held the model (DeepSeek V4.1 Flash), the agent loop and the memory content fixed and changed only how the agent reaches its memory. On LongMemEval, a benchmark of questions about long chat histories, we compared the runtime's own session search (as shipped and with shortened output), a sandboxed shell with sqlite3 and grep, a compact memory tool with BM25, dense or hybrid scoring, prefetching results into the prompt, and the full history in the prompt, on 180 questions. We repeated five of them on 42 questions whose histories are ten times longer (about 1.5 million tokens each).
To test sharing, we split each history across six agents: one asks, three share their memory, two keep it private. The question's evidence sits with a public agent (120 questions) or a private one (42 questions). The asking agent either searches only its own store, searches each colleague's store in turn, asks colleagues by message, searches one shared index through its view, or searches the shared index with no view at all, with or without an instruction to keep private memory private.
Finally, we benchmarked the index itself on one host: Redis 8 (query engine and vector sets), PostgreSQL with pgvector, and SQLite full-text search, with views of different sizes. Every model call went through one metering proxy on the shared pool; all runs together cost 54.94 yuan.
What we found
Tokens halve, but the interface does it, not the vectors. The hybrid memory tool used 0.51× the tokens of the runtime's session search, with the same number of model calls and about the same time. Its accuracy was 1.7 points lower (92.2% against 93.9%): the difference is not significant, but the test cannot rule out a loss of up to 5.6 points. BM25 behind the same compact interface saved even more (0.42×). The runtime's tool returns whole windows of earlier messages for every search; a compact list of dated matches does not. Shortening the runtime's own output saved as many tokens but cost 6.7 points, so short results alone are not enough. Dense scoring alone was not more accurate than BM25.
Agents did not search less. The memory tool needed as many model calls as session search, about 2.66 per question. Prefetching the best eight results into the prompt answered in one call with less than a tenth of the tokens, but was 13.9 points less accurate; it lost most often on questions that combine several sessions.
Longer histories hurt hybrid scoring most. With ten times more history, every method lost accuracy: BM25 4.8 points, session search 11.9 and hybrid scoring 21.4. The evidence was still found; what changed is that look-alike memories from other conversations crowded it out or entered the answer. On 42 questions this is suggestive, not proven.
Sharing works, and the view keeps it safe. With only its own store, the asking agent answered 1.7% of the questions whose evidence a colleague held; through the shared view, 91.7%. Asking colleagues by message reached about the same accuracy (90.0%) with 75.4k tokens and 13.8 s per question, five times the cost and time of the shared view. With the view checked in the index, no private record reached any agent's context; without it, private evidence reached the context in every private question and the agent repeated it in 39 of 42. An instruction not to reveal private memory changed the answers but not the context: 1,523 private records still reached the agent across the 42 questions.
At this scale the backend is not the bottleneck, but its filter matters. Every index answered within about 20 milliseconds, against one to two seconds for a model call. What decides recall is how the index applies the view: filtering after an approximate search, pgvector's default, returned fewer than ten results for 163 of 180 single-agent queries (recall 0.291); filtering first, or pgvector's iterative scans, kept recall near exact. At the size of a real deployment, the memory needed for the vectors, not speed, becomes the first limit.
What it means
For a team of agents, the order of work is clear. First give agents a compact way to read their memory; that halves the cost of recall without any new database, but check accuracy on your own questions. Then put the organisation's memory in one index with views, which is what lets agents use each other's knowledge without messages and without leaking. Choose the backend for its filtering behaviour and operations, not its speed, and keep checking dense scoring on your own data: our benchmark is English and keyword-friendly, while real agent memory is multilingual and paraphrased. Our next study asks how such a shared memory should be maintained: what to write, merge and retire as agents join and leave.
Read the full paper
Read the full working paper: the formal model, the benchmarks, fifteen conditions and all results.
The full paper is in English.
Cite this work
Yanming Guo, Haixin Wang, Yanjun Lu (2026). Memory as a Shared Space: Retrieval Interfaces and View-Filtered Indexes for Persistent Agents. AIDC Research. https://www.ai-dc.ai/research/shared-memory-space
@techreport{guo2026shared,
  title       = {Memory as a Shared Space: Retrieval Interfaces and View-Filtered Indexes for Persistent Agents},
  author      = {Guo, Yanming and Wang, Haixin and Lu, Yanjun},
  institution = {AIDC Research},
  year        = {2026},
  type        = {Research paper},
  url         = {https://www.ai-dc.ai/research/shared-memory-space}
}